
Linux Memory Forensics: Deconstructing eBPF Rootkit Mechanics

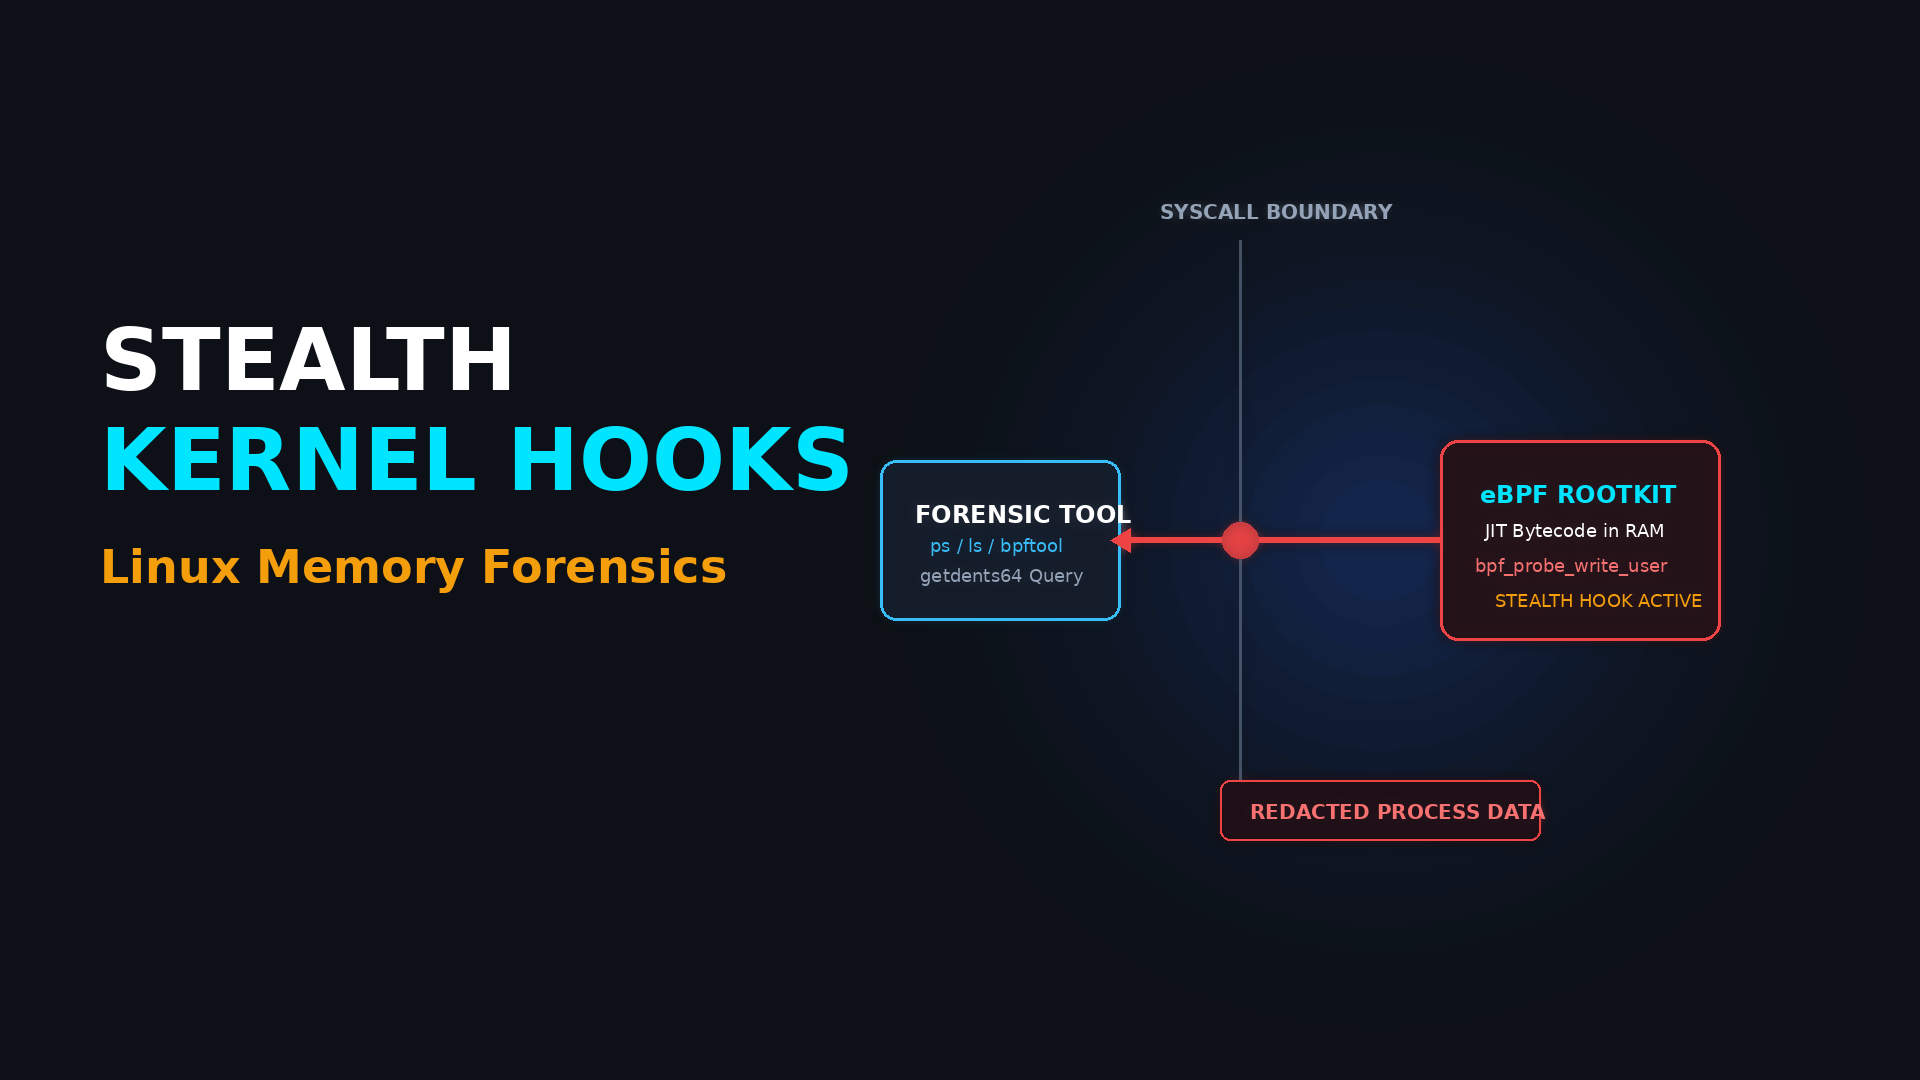
Overview & Threat Landscape#
For decades, Linux kernel rootkits relied on Loadable Kernel Modules (LKMs) to manipulate syscall tables, intercept process execution, and hide adversarial presence. However, modern infrastructure hardening—specifically cryptographically enforced module signing (CONFIG_MODULE_SIG_FORCE) and lockdown modes—has severely constrained unsigned LKM deployment. In response, advanced threat groups have transitioned to an intrinsically trusted in-kernel execution environment: eBPF (Extended Berkeley Packet Filter).
Rather than loading traditional kernel drivers, eBPF rootkits (such as TripleCross and Symbiote-adjacent variants) leverage legitimate kernel tracing infrastructure. Using privileged program types like BPF_PROG_TYPE_KPROBE, BPF_PROG_TYPE_TRACEPOINT, and BPF_PROG_TYPE_LSM, adversaries hook critical syscall trampolines to tamper with user-space memory, alter return values, and conceal running processes, open network sockets, and persistence files.
[!WARNING] eBPF rootkits execute entirely within verified kernel execution rings without appearing in
lsmodor/proc/modules. Because they hook function entry and exit points via BPF trampolines, traditional user-space forensic tools (ps,netstat,lsof) receive manipulated data directly from the kernel, creating a profound visibility blind spot during incident response.
Vulnerability & Attack Root-Cause Analysis#
The weaponization of eBPF stems from the extensive capabilities granted to specific in-kernel helper functions when eBPF programs run with CAP_BPForCAP_SYS_ADMIN privileges:
- Syscall Return Value Tampering (
bpf_override_return): Designed for kernel error injection testing, this helper permits an attached BPF program to modify the return code of an underlying kernel function. Rootkits attach to__x64_sys_getdents64and selectively redact directory entries matching malicious file names or PID directories in/proc. - User-Space Memory Mutation (
bpf_probe_write_user): This helper allows an in-kernel eBPF program to write directly into the virtual address space of the current user-space process. Attackers use this to patch/etc/sudoersor PAM authentication buffers on the fly whensudoexecutes, granting root access without touching disk files. - Telemetry Blinding via Map Unlinking: Attackers can unload or detach user-space control daemons while leaving the verified eBPF bytecode pinned in the BPF Virtual File System (
/sys/fs/bpf) or active in anonymous kernel memory links (bpf_link), making discovery via standardbpftool prog listelusive if the tool itself is intercepted.
sequenceDiagram
    autonumber
    participant UserApp as Forensic Utility (ps / ls / bpftool)
    participant VFS as Virtual File System (getdents64)
    participant Trampoline as BPF Trampoline Hook (__x64_sys_getdents64)
    participant RootkitProg as In-Memory eBPF Rootkit
    participant BPFMap as BPF Hidden PID Hash Map

    UserApp->>VFS: Query directory contents for /proc
    VFS->>Trampoline: Execute native getdents64 syscall
    Trampoline->>RootkitProg: Trigger kretprobe callback
    RootkitProg->>BPFMap: Check if returned PIDs match hidden malicious process
    Note over RootkitProg,BPFMap: Match identified: PID 4821 belongs to adversary C2 daemon
    RootkitProg->>RootkitProg: Overwrite dirent buffer using bpf_probe_write_user
    Note over RootkitProg,UserApp: Unlink entry and shift subsequent record offsets
    RootkitProg-->>UserApp: Return redacted directory structure to user space
    Note over UserApp: Forensic tool displays clean output with zero evidence of PID 4821
Exploit Architecture & Memory Hook Footprint#
The diagram below details the operational layout of an eBPF rootkit residing in volatile Linux memory:
flowchart TD
    subgraph UserSpace ["User-Space Architecture"]
        LoaderProc["Rootkit Loader (Detached / Terminated)"]
        UserTools["Forensic Tools: ps / lsof / bpftool"]
    end

    subgraph KernelCore ["Linux Kernel Ring-0 Execution"]
        SyscallBoundary["Syscall Dispatcher: __x64_sys_*"]
        TrampolineGate["Ftrace / BPF JIT Trampoline Hook"]
        BPFProgram["Verified eBPF Bytecode (JIT-Compiled)"]
        BPFLink["struct bpf_link Kernel Descriptor"]
        StorageMaps["BPF Hash Maps: Hidden Artifacts Registry"]
    end

    subgraph MemoryArtifacts ["Physical Volatile Memory (RAM)"]
        AnonMemory["Unbacked JIT Executable Pages"]
        KernelStructs["bpf_prog and bpf_map Memory Structures"]
    end

    LoaderProc -->|bpf syscall: BPF_PROG_LOAD| BPFProgram
    BPFProgram --> BPFLink
    BPFLink --> TrampolineGate
    TrampolineGate --> SyscallBoundary
    SyscallBoundary -.->|Altered Return Data| UserTools
    BPFProgram <--> StorageMaps
    BPFProgram --> AnonMemory
    BPFLink --> KernelStructs
Attack Path Step-by-Step#
Consider how an adversary deploys an eBPF rootkit to hide a cryptominer or reverse shell from system administrators.
Step 1: Compiling the In-Kernel Hook Program#
The attacker authors a restricted C program utilizing libbpf and BPF CO-RE (Compile Once, Run Everywhere):
#include "vmlinux.h"
#include <bpf/bpf_helpers.h>
#include <bpf/bpf_tracing.h>

char LICENSE[] SEC("license") = "Dual BSD/GPL";

struct {
    __uint(type, BPF_MAP_TYPE_HASH);
    __uint(max_entries, 64);
    __type(key, u32);
    __type(value, u8);
} hidden_pids SEC(".maps");

SEC("kretprobe/__x64_sys_getdents64")
int BPF_KRETPROBE(hook_getdents64, struct linux_dirent64 *dirent)
{
    // Educational proof-of-concept:
    // When getdents64 returns directory entries for /proc,
    // the program inspects dirent->d_name.
    // If d_name matches a PID registered in hidden_pids,
    // it recalculates dirent record offsets to conceal the process.
    return 0;
}
Step 2: Injecting and Pinning the Program#
The adversary loads the compiled bytecode into the kernel using the bpf() system call and pins the program to retain persistence:
# Loading and pinning the rootkit into kernel memory
bpftool prog load bpf_rootkit.o /sys/fs/bpf/sys_monitor type tracepoint
bpftool map update pinned /sys/fs/bpf/hidden_pids key hex 25 12 00 00 value hex 01

## The loader binary terminates, leaving no active process running on the host
rm -f ./loader
Step 3: Evading Standard Detection#
When an incident responder runs ps auxortop, the in-kernel hook intercepts the directory walk over /proc/4821, unlinking the dirent struct. The process continues executing in background memory, communicating with external command-and-control servers while invisible to the operating system's process table.
[!CAUTION] If the rootkit also hooks
__x64_sys_bpf, it can filter queries directed at thebpf()syscall itself, preventing evenbpftool prog showfrom listing the loaded hook.
Fast Cyber Defense Morning Takeaways#
- Kernel Tracing Tools Are Dual-Use: eBPF's immense observability power makes it an equally potent stealth platform. Security teams cannot assume in-kernel hooks are strictly defensive.
- User-Space Forensics Cannot Be Trusted: Once a root-level attacker deploys an eBPF hook, user-space inspection tools (
ps,ss,auditd) can be blinded at the syscall boundary. - Volatile Memory Acquisition Is Essential: Detecting advanced eBPF rootkits requires capturing raw physical memory (via LiME or crash dumps) and parsing kernel structures (
bpf_prog,bpf_link) independently of live syscall APIs.
Tonight in EDITION 2 (Night, 8:45 PM BST), we will publish the companion blue team guide:
- Memory acquisition workflows using LiME (Linux Memory Extractor) on modern kernels.
- Developing custom Volatility 3 plugins to traverse unlinked
bpf_progandbpf_linkstructs. - Hardening Linux kernels by restricting unprivileged eBPF and auditing JIT allocation pages via eBPF-LSM verification.
Comments
Post a Comment